A global biotech company replaces Informatica IDQ and scales data quality across multiple business units
A global pharmaceutical and diagnostics company replaced a multi-year Informatica IDQ deployment with Ataccama. The move happened alongside a transformation program that retired the company’s SAP ERP system. Today the program runs on Snowflake, covers four business units, and is delivered through a defined process that involves business teams end to end, from business problem statement through profiling and rule creation to remediation.
| Industry | Life sciences (pharmaceuticals and diagnostics) |
| Company profile | Global manufacturer with geographically distributed production and centralized purchasing |
| Ataccama capabilities | Data quality and catalog (DQ&C), data profiling, monitoring |
| Core platforms | Snowflake, Oracle Database, Amazon S3, Amazon Aurora PostgreSQL, AWS |
| Previous solution | Informatica IDQ, deployed over several years |
| Business units covered | People and culture, supply chain, regulatory, clinical |
Results at a glance
19
Data source systems covered
450
Data quality rules in production
38
Monitoring projects
36000
Catalog items profiled
190
Tables monitored
92
Users across four business units
Situation
The company is a global biotech organization operating across pharmaceuticals and diagnostics. Manufacturing is distributed geographically while purchasing is run centrally. That split fragments information about which materials are used, how they are used, and to what extent.
The technical team receives raw data from plants and manufacturing facilities, covering plant, material, packaging, and shipping records. The team was responsible for preparing that data, applying quality controls, and reporting on it for supply chain planning.
Data quality had been governed by Informatica IDQ, connected to the company’s SAP ERP system and running checks on the data held there. Then a transformation program retired that ERP system altogether and the company built a dedicated data quality database that the source systems export into. That database runs on Snowflake, holding data from people and culture, regulatory, pharma technical operations covering logistics and supply chain, and clinical.
Leadership had set a clear direction: accurate reporting and fast resolution of quality issues across different business areas, so that operations and reporting run more smoothly.
Challenge
Existing solutions were already in place, but tight budgets and growing market demand pushed the organization to modernize its stack. It needed reliable, high quality data available faster to support better decisions and to optimize the supply chain.
Data challenges that led to the evaluation
| Challenge | What it meant day to day |
|---|---|
| Incorrect and inconsistent information | Supply chain reporting inherited errors from the source, so downstream analysis needed manual correction |
| The data quality program was IT driven rather than business centric | Business teams had limited ownership |
| Heavy dependency on IT for data quality maintenance | Every rule change and manual correction went through a technical queue, which was resource intensive and slow |
| No path to scale the program enterprise wide | The program could not extend beyond its original scope without adding proportional IT effort |
Why Informatica IDQ was replaced
The organization had been an Informatica IDQ customer for several years. The business team could not scale with it because the tooling was not business friendly. Reliance on IT created a backlog, kept work manual, and made the approach to data quality reactive rather than preventive. The team wanted high quality data available faster to support efficient decision making.
| Dimension | Before | After |
|---|---|---|
| Rule ownership | IT team authored and maintained rules | Business & technical teams define and own rules |
| Operating model | Reactive, driven by reported issues | Monitored, with issues surfaced continuously |
| Throughput | Change requests queued behind IT backlog | Business-led changes without a technical queue |
| Effort profile | Manual tasks across preparation and control | Automated checks and scheduled monitoring |
| Scalability | Limited beyond the original scope | Extended across 19 source systems and 38 monitoring projects |
Solution
The organization migrated from Informatica IDQ to Ataccama ONE as part of an enterprise SAP transformation program.
- Ataccama ONE is used to define rules, run checks on data, and route the issues those checks raise into stewardship workflows for resolution.
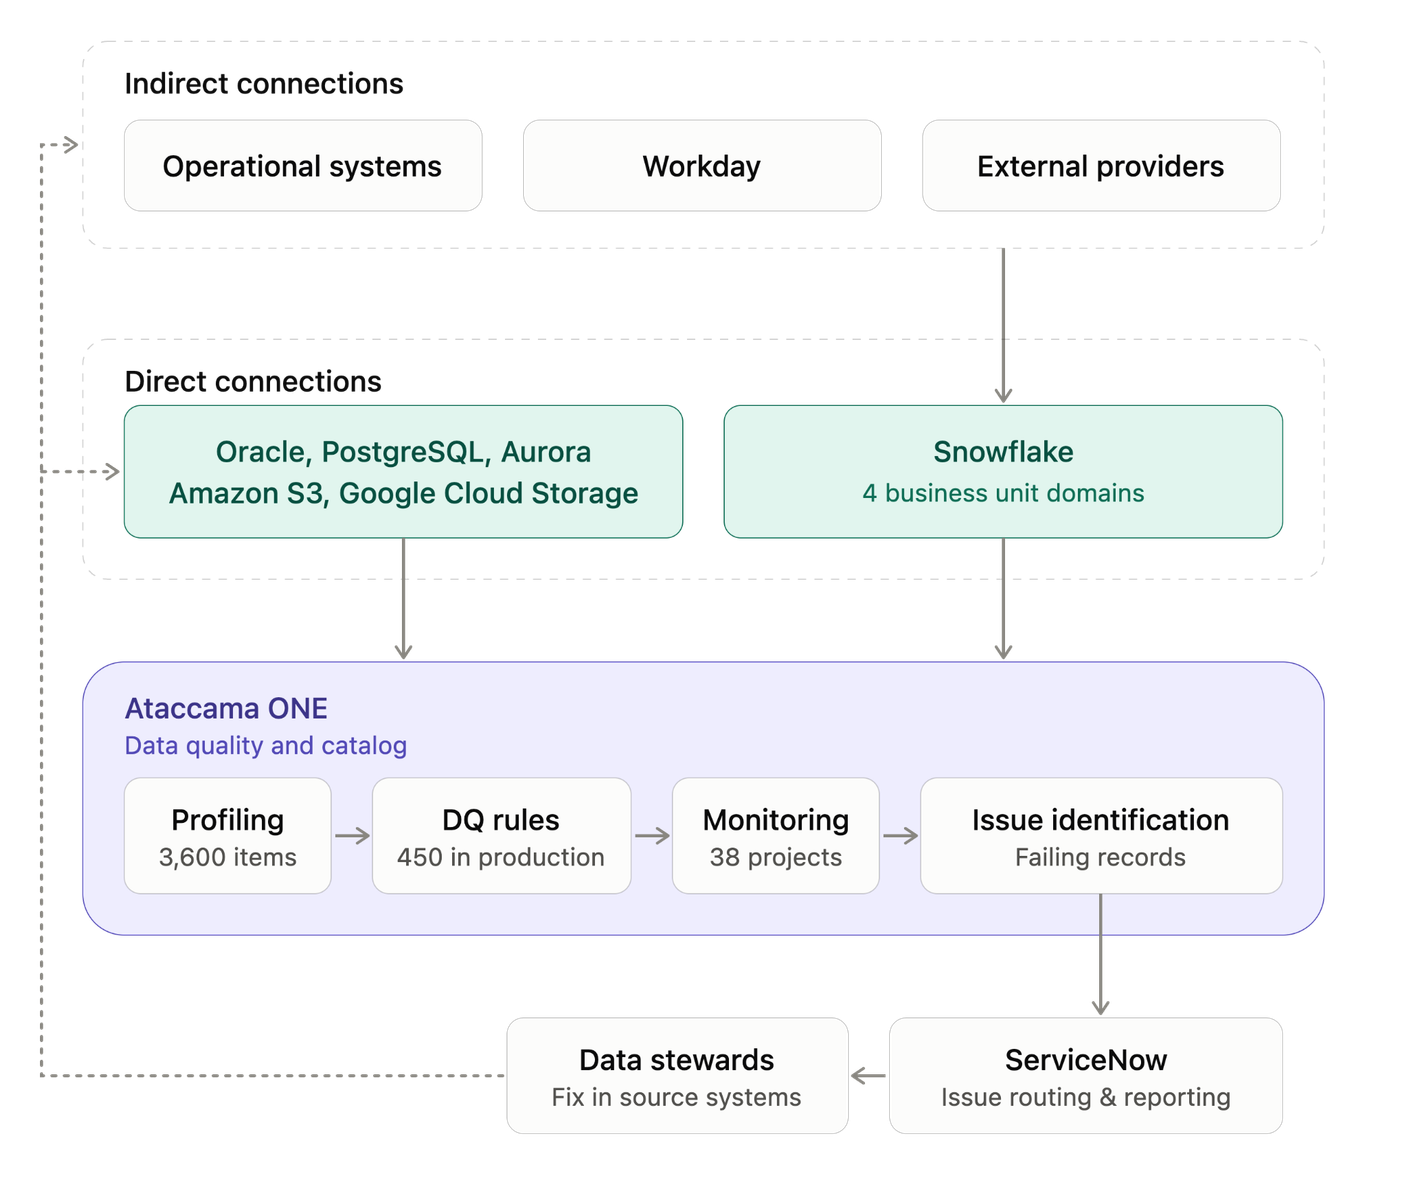
- Data quality rules are applied to data residing in Snowflake before it moves into reporting systems. A dedicated data quality database in Snowflake is populated by automated exports from the operational systems across the covered domains.
- A monitoring layer runs across the four business units and their use cases, so data quality is measured continuously rather than resolved reactively.
- Failing records are exported to the team that has to correct them in the source systems.
Environment summary
| Direct connections | Snowflake, Amazon Aurora PostgreSQL, PostgreSQL, Google Cloud Storage, Amazon S3 buckets, Oracle Database |
| Indirect connections | Workday, External sources, External payroll information providers – exported to DQ database in Snowflake |
| Integrations | ServiceNow, Airtable, SharePoint |
| Domains covered | People & Culture, Regulatory, Pharma technical operations covering Logistics & Supply chain data, Clinical data, |
From business problem to fixed record: how each use case is delivered
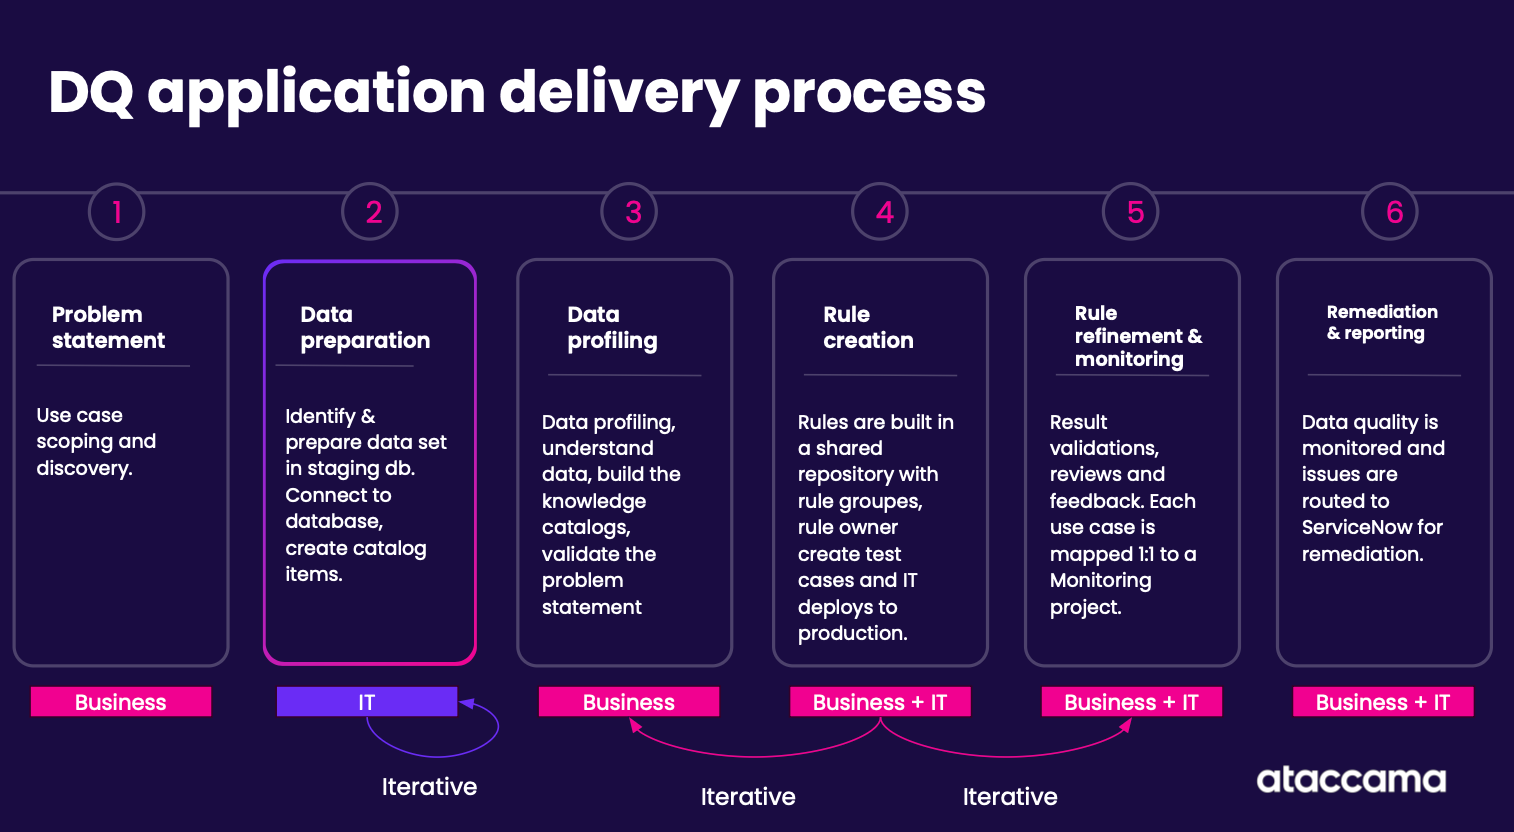
Under Informatica IDQ, every rule change and every manual correction went through IT, which kept data quality IT-centric and reactive. To move data quality to shared ownership, the company now takes each new use case through the same six-stage delivery process, in all four business units. Every stage has a named owner: the business, IT, or both. That makes the line clear between the work business teams now do themselves and the work that still needs technical skill.
1. Problem statement and use case scoping (Business)
Every use case starts with a business problem, before anyone touches data. The business unit defines which process is at stake and what happens when it goes wrong: a delayed delivery, an incorrect payroll record, a submission that has to be repeated. The goal is to tie each data quality check to something the business already cares about, not to a technical data question.
This is how the program addressed the limited business ownership it had before. A use case with a stated business problem has an owner, a way to judge whether its rules are working, and a reason to keep them maintained. It also makes the value of each check easy to show: a check is worth the cost of the failure it prevents.
The people and culture unit has scoped use cases covering payroll, compensation, and employee master data. Pharma technical operations has raised the broadest set, across supply chain and logistics.
2. Data preparation (IT)
This is the only stage IT owns on its own. The technical team identifies the data set, prepares it in a staging database, connects Ataccama ONE to it, and creates the catalog items the rest of the process works from. Standard tables come in directly. Use cases that need attributes from more than one table depend on correct joins, and a wrong join produces data that looks complete but is less trustworthy than the original. That is why this stage stays technical and repeats until the data set is right.
3. Data profiling (Business)
With the data in place, the business team checks that it is looking at the right thing. Profiling here is not a quality assessment. It answers whether a table holds the content the team expects, not whether that content is correct. A column named customer can contain identifiers rather than names, or hold only the customers of another business unit. When the same entity exists in ten systems, profiling is how the team works out which table to point at before anyone writes a rule. It is also where the business validates the problem statement from stage 1 and builds the knowledge catalog. Across the program, 3,600 catalog items have been profiled.
4. Rule creation (Business + IT)
This is where the move away from the IT queue shows most clearly. Business teams build simple and mid-complexity rules themselves, such as checks on whether a field is populated. Aggregation rules and nested conditional logic go to IT. Rules sit in a shared repository, organized into rule groups. The rule owner creates the test cases, and IT deploys the rule to production. Because Ataccama ONE supports both sides of the split, a business team can work on a rule without immediate IT support. The program now has 450 rules in production.
5. Rule refinement & monitoring
Business and IT validate and review the results, then feed what they find back into the rules. Profiling, rule creation, and refinement run as a loop until the results are right. Each use case maps to its own monitoring project. A business process usually depends on more than one table, so grouping catalog items by the process they serve keeps results readable and tied to the problem defined in stage 1. This is how the company replaced reactive fixes with continuous monitoring. There are now 38 monitoring projects in place, with 190 tables monitored.
6. Remediation and reporting (Business + IT)
This stage closes the loop with the source systems. Failing records are routed to ServiceNow as tickets. Routing uses metadata already held in Ataccama ONE, including the business line, so each ticket reaches the domain that owns the data.
Each ticket names the use case, the record identifier, and the rules the record failed, with a description of the correction needed. Data stewards work the queue in ServiceNow and fix the record in the source system. The error is corrected once, at source, instead of being corrected by hand in downstream analysis as it was before.
Outcomes
Proactive monitoring and maintenance of high-quality data, supported by a process that is scalable and automated, with business teams involvement.
Business benefits
- Cost reduction through a modernized technology stack.
- Accurate and timely reporting across four business units.
- A data quality program that business teams own and can extend without proportional IT effort.
- Issues that reach the person who can correct them in the source systems, with the failing records attached.
Conclusion
Operational issues are what the business feels day to day. A failing record now arrives as a ticket that names the use case, the record, and the rule it failed, routed to the domain that owns the data. The preparation and manual correction that used to sit with the technical team is handled by monitoring projects, and issues surface early enough to be corrected at source rather than waiting to be reported after they have affected downstream reports or operations.
That holds because the operating model changed. Business teams profile their own data and write their own rules, with IT supporting them on the more sophisticated ones. Across 19 source systems and 450 rules covering four business units, data quality is no longer a queue in front of IT.
The program was funded on cost, and modernizing the stack was where the savings were expected. Rebuilding data quality against the new sources gave the company a design that fits how its data moves now, which is what lets it extend to the next domain without proportional IT effort.
Let’s chat
We’d love to walk you though more details. Set up some time to talk with our team.
A global pharmaceutical and diagnostics company replaced a multi-year Informatica IDQ deployment with Ataccama. The move happened alongside a transformation program that retired the company’s SAP ERP system. Today the program runs on Snowflake, covers four business units, and is delivered through a defined process that involves business teams end to end, from business problem statement through profiling and rule creation to remediation.
| Industry | Life sciences (pharmaceuticals and diagnostics) |
| Company profile | Global manufacturer with geographically distributed production and centralized purchasing |
| Ataccama capabilities | Data quality and catalog (DQ&C), data profiling, monitoring |
| Core platforms | Snowflake, Oracle Database, Amazon S3, Amazon Aurora PostgreSQL, AWS |
| Previous solution | Informatica IDQ, deployed over several years |
| Business units covered | People and culture, supply chain, regulatory, clinical |
Results at a glance
19
Data source systems covered
450
Data quality rules in production
38
Monitoring projects
36000
Catalog items profiled
190
Tables monitored
92
Users across four business units
Situation
The company is a global biotech organization operating across pharmaceuticals and diagnostics. Manufacturing is distributed geographically while purchasing is run centrally. That split fragments information about which materials are used, how they are used, and to what extent.
The technical team receives raw data from plants and manufacturing facilities, covering plant, material, packaging, and shipping records. The team was responsible for preparing that data, applying quality controls, and reporting on it for supply chain planning.
Data quality had been governed by Informatica IDQ, connected to the company’s SAP ERP system and running checks on the data held there. Then a transformation program retired that ERP system altogether and the company built a dedicated data quality database that the source systems export into. That database runs on Snowflake, holding data from people and culture, regulatory, pharma technical operations covering logistics and supply chain, and clinical.
Leadership had set a clear direction: accurate reporting and fast resolution of quality issues across different business areas, so that operations and reporting run more smoothly.
Challenge
Existing solutions were already in place, but tight budgets and growing market demand pushed the organization to modernize its stack. It needed reliable, high quality data available faster to support better decisions and to optimize the supply chain.
Data challenges that led to the evaluation
| Challenge | What it meant day to day |
|---|---|
| Incorrect and inconsistent information | Supply chain reporting inherited errors from the source, so downstream analysis needed manual correction |
| The data quality program was IT driven rather than business centric | Business teams had limited ownership |
| Heavy dependency on IT for data quality maintenance | Every rule change and manual correction went through a technical queue, which was resource intensive and slow |
| No path to scale the program enterprise wide | The program could not extend beyond its original scope without adding proportional IT effort |
Why Informatica IDQ was replaced
The organization had been an Informatica IDQ customer for several years. The business team could not scale with it because the tooling was not business friendly. Reliance on IT created a backlog, kept work manual, and made the approach to data quality reactive rather than preventive. The team wanted high quality data available faster to support efficient decision making.
| Dimension | Before | After |
|---|---|---|
| Rule ownership | IT team authored and maintained rules | Business & technical teams define and own rules |
| Operating model | Reactive, driven by reported issues | Monitored, with issues surfaced continuously |
| Throughput | Change requests queued behind IT backlog | Business-led changes without a technical queue |
| Effort profile | Manual tasks across preparation and control | Automated checks and scheduled monitoring |
| Scalability | Limited beyond the original scope | Extended across 19 source systems and 38 monitoring projects |
Solution
The organization migrated from Informatica IDQ to Ataccama ONE as part of an enterprise SAP transformation program.
- Ataccama ONE is used to define rules, run checks on data, and route the issues those checks raise into stewardship workflows for resolution.
- Data quality rules are applied to data residing in Snowflake before it moves into reporting systems. A dedicated data quality database in Snowflake is populated by automated exports from the operational systems across the covered domains.
- A monitoring layer runs across the four business units and their use cases, so data quality is measured continuously rather than resolved reactively.
- Failing records are exported to the team that has to correct them in the source systems.
Environment summary
| Direct connections | Snowflake, Amazon Aurora PostgreSQL, PostgreSQL, Google Cloud Storage, Amazon S3 buckets, Oracle Database |
| Indirect connections | Workday, External sources, External payroll information providers – exported to DQ database in Snowflake |
| Integrations | ServiceNow, Airtable, SharePoint |
| Domains covered | People & Culture, Regulatory, Pharma technical operations covering Logistics & Supply chain data, Clinical data, |
From business problem to fixed record: how each use case is delivered
Under Informatica IDQ, every rule change and every manual correction went through IT, which kept data quality IT-centric and reactive. To move data quality to shared ownership, the company now takes each new use case through the same six-stage delivery process, in all four business units. Every stage has a named owner: the business, IT, or both. That makes the line clear between the work business teams now do themselves and the work that still needs technical skill.
1. Problem statement and use case scoping (Business)
Every use case starts with a business problem, before anyone touches data. The business unit defines which process is at stake and what happens when it goes wrong: a delayed delivery, an incorrect payroll record, a submission that has to be repeated. The goal is to tie each data quality check to something the business already cares about, not to a technical data question.
This is how the program addressed the limited business ownership it had before. A use case with a stated business problem has an owner, a way to judge whether its rules are working, and a reason to keep them maintained. It also makes the value of each check easy to show: a check is worth the cost of the failure it prevents.
The people and culture unit has scoped use cases covering payroll, compensation, and employee master data. Pharma technical operations has raised the broadest set, across supply chain and logistics.
2. Data preparation (IT)
This is the only stage IT owns on its own. The technical team identifies the data set, prepares it in a staging database, connects Ataccama ONE to it, and creates the catalog items the rest of the process works from. Standard tables come in directly. Use cases that need attributes from more than one table depend on correct joins, and a wrong join produces data that looks complete but is less trustworthy than the original. That is why this stage stays technical and repeats until the data set is right.
3. Data profiling (Business)
With the data in place, the business team checks that it is looking at the right thing. Profiling here is not a quality assessment. It answers whether a table holds the content the team expects, not whether that content is correct. A column named customer can contain identifiers rather than names, or hold only the customers of another business unit. When the same entity exists in ten systems, profiling is how the team works out which table to point at before anyone writes a rule. It is also where the business validates the problem statement from stage 1 and builds the knowledge catalog. Across the program, 3,600 catalog items have been profiled.
4. Rule creation (Business + IT)
This is where the move away from the IT queue shows most clearly. Business teams build simple and mid-complexity rules themselves, such as checks on whether a field is populated. Aggregation rules and nested conditional logic go to IT. Rules sit in a shared repository, organized into rule groups. The rule owner creates the test cases, and IT deploys the rule to production. Because Ataccama ONE supports both sides of the split, a business team can work on a rule without immediate IT support. The program now has 450 rules in production.
5. Rule refinement & monitoring
Business and IT validate and review the results, then feed what they find back into the rules. Profiling, rule creation, and refinement run as a loop until the results are right. Each use case maps to its own monitoring project. A business process usually depends on more than one table, so grouping catalog items by the process they serve keeps results readable and tied to the problem defined in stage 1. This is how the company replaced reactive fixes with continuous monitoring. There are now 38 monitoring projects in place, with 190 tables monitored.
6. Remediation and reporting (Business + IT)
This stage closes the loop with the source systems. Failing records are routed to ServiceNow as tickets. Routing uses metadata already held in Ataccama ONE, including the business line, so each ticket reaches the domain that owns the data.
Each ticket names the use case, the record identifier, and the rules the record failed, with a description of the correction needed. Data stewards work the queue in ServiceNow and fix the record in the source system. The error is corrected once, at source, instead of being corrected by hand in downstream analysis as it was before.
Outcomes
Proactive monitoring and maintenance of high-quality data, supported by a process that is scalable and automated, with business teams involvement.
Business benefits
- Cost reduction through a modernized technology stack.
- Accurate and timely reporting across four business units.
- A data quality program that business teams own and can extend without proportional IT effort.
- Issues that reach the person who can correct them in the source systems, with the failing records attached.
Conclusion
Operational issues are what the business feels day to day. A failing record now arrives as a ticket that names the use case, the record, and the rule it failed, routed to the domain that owns the data. The preparation and manual correction that used to sit with the technical team is handled by monitoring projects, and issues surface early enough to be corrected at source rather than waiting to be reported after they have affected downstream reports or operations.
That holds because the operating model changed. Business teams profile their own data and write their own rules, with IT supporting them on the more sophisticated ones. Across 19 source systems and 450 rules covering four business units, data quality is no longer a queue in front of IT.
The program was funded on cost, and modernizing the stack was where the savings were expected. Rebuilding data quality against the new sources gave the company a design that fits how its data moves now, which is what lets it extend to the next domain without proportional IT effort.
Let’s chat
We’d love to walk you though more details. Set up some time to talk with our team.